The Paradime Discovery API: query your dbt™ metadata over GraphQL
Every Bolt run builds a picture of your data platform - how the project fits together, what ran, what broke, and what landed in the warehouse. The Discovery API makes that picture queryable.
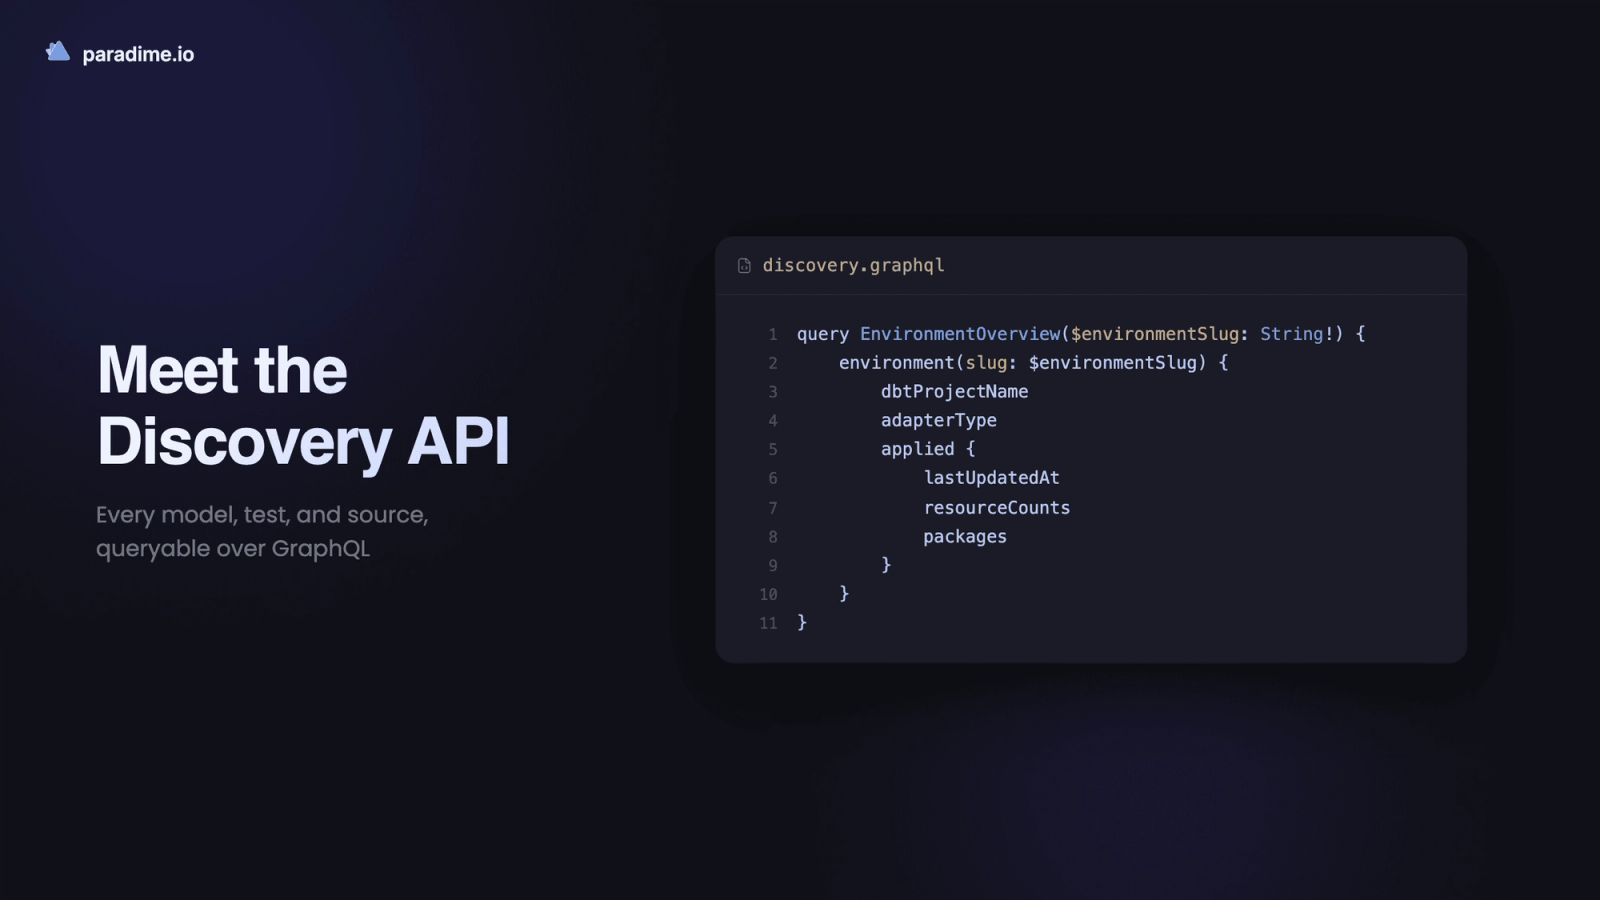
Every time Bolt runs your dbt™ project, it builds a picture of your data platform: how the project fits together, what ran and how long it took, which tests passed, how fresh the sources were, and what the resulting tables actually look like in the warehouse.
Until now, that picture was something you looked at. It's in the Paradime UI, it's behind the Radar dashboards, and it's what DinoAI reads when you ask it about your project. The Discovery API makes it something you can query directly.
It's a GraphQL endpoint over the metadata Paradime is already collecting on every run, which means the answers to questions like when did this table last update, what breaks if I change this, and which model is quietly costing us the most are a request away - no parsing manifest.json, no scraping run logs, no separate metadata pipeline to keep alive.
Available now to any workspace with an API key carrying the Discovery API Viewer capability.
Why we built this
Agents work differently compared to humans. Humans need visual UI to consume information. Agents need information to reason and do meaningful work with that information. Humans are then using these agents to synthesize that information from the tools they use - their IDE, Co-pilot app, Terminal UI, and mobile phone and even wearables. Everyone is looking for the same kind of information but from extremely different places.
At Paradime, we are building the essential agentic infrastructure for data engineering teams. To make that a reality we need to make the metadata generated in Paradime machine query-able and readable as a state machine i.e. we need to know the current state of the dbt™ project and the state transitions it took to get there.
How queries are structured
Every query starts from environment, identified by its slug. Underneath, it's a state machine: each environment gives you a current state and a way to walk back through how it got there.
definition- the state of the project as declared in code, parsed from the latest manifest. This is what you meant.applied- the state after execution: run status, timing, test results, source freshness, and catalog metadata. This is what actually happened.
Each Bolt run is a transition. A model builds, a test passes or fails, a source loads or doesn't - and applied reflects whatever state that run left the project in. modelHistoricalRuns steps back through those transitions one run at a time, so instead of one snapshot you get the sequence that produced it.
Monitoring work almost always wants applied, because it tracks the state the pipeline is actually in. Governance and documentation work tends to want definition, because it describes the state the project claims for itself, whether or not it has run recently. And the two can drift: a model whose committed SQL (definition) no longer matches the SQL that last ran (applied) is one you'll want to look at before someone else notices.
A first request looks like this:
import requests

api_endpoint = "<YOUR_API_ENDPOINT>"
api_token = "<YOUR_API_TOKEN>"        # account API key, starts with prdm_cmp_
workspace_uid = "<YOUR_WORKSPACE_UID>"

graphql_query = """
query EnvironmentOverview($environmentSlug: String!) {
    environment(slug: $environmentSlug) {
        dbtProjectName
        adapterType
        applied {
            lastUpdatedAt
            resourceCounts
            packages
        }
    }
}
"""

response = requests.post(
    api_endpoint,
    json={"query": graphql_query, "variables": {"environmentSlug": "production"}},
    headers={
        "Content-Type": "application/json",
        "Authorization": f"Bearer {api_token}",
        "X-Paradime-Workspace": workspace_uid,
    },
)

print(response.json())
and the response:
{
  "data": {
    "environment": {
      "dbtProjectName": "demo_sales_project",
      "adapterType": "snowflake",
      "applied": {
        "lastUpdatedAt": "2026-08-06T02:14:33+00:00",
        "resourceCounts": "{\"model\": 24, \"source\": 4, \"test\": 38, \"seed\": 2, \"snapshot\": 1, \"exposure\": 3}",
        "packages": ["demo_sales_project", "dbt_utils"]
      }
    }
  }
}
Connection fields (models, sources, tests, and so on) are cursor-paginated: pass first to set page size, after with the previous page's pageInfo.endCursor to advance, and read totalCount when you need the denominator.
Coming from the dbt Cloud™ Discovery API
The two APIs answer the same family of questions, and we deliberately kept the vocabulary close - environment, definition, applied, executionInfo, modelHistoricalRuns all mean what you'd expect. Most queries port over with small edits. Here's what those edits are.
Paradime Discovery API | dbt Cloud™ Discovery API | ||
|---|---|---|---|
Metadata source | Bolt runs in your workspace | dbt Cloud™ job runs | |
Entry point |
|
| |
Job-level queries | Environment only. | Separate | |
Auth | Account API key as a Bearer token plus | Metadata Only service token | |
Filter values | Plain strings: | Enums: | |
Walking lineage |
| Nested nodes are unions; you write | |
Whole-DAG traversal | The flat | Query a generation at a time - children, then their children | |
Exposure health | Precomputed rollup on the exposure: | Query the exposure's parents and derive the rollup yourself | |
Warehouse join key |
|
| |
Catalog refresh |
| Catalog refreshes with docs generation in a job | |
History window | Governed by your Bolt run history | Documented as the previous two months |
If you're porting a script from the dbt Cloud™ API: strip the inline fragments, quote your filter values, swap the environment ID for a slug, and check whether the thing you were computing client-side - an exposure's health, a full lineage walk - is already a field here.
Five things teams use it for
Use case | Outcome | Example questions |
|---|---|---|
Performance | Find inefficiencies in pipeline execution to cut warehouse spend and deliver data earlier | What's the latest status of each model? Does this model need to run at all? How long did each model take? |
Quality | Monitor source freshness and test results to catch and resolve issues | How fresh are my sources? Which models and tests failed? What's my test coverage? |
Discovery | Find and understand datasets with real context attached | What do this table and its columns mean? What's the full lineage of this model? Which metrics are defined? |
Governance | Audit development and make ownership legible across teams | Who owns this model? How do I reach them? Who is allowed to build on it? |
Development | Understand how datasets change and where they're used before you touch them | Which dashboards depend on this? What depends on this source? How has this model changed? |
Below are four worked examples, followed by the Python and agent patterns built on top of them.
Example 1: attribute warehouse cost to models
Start with execution time across the DAG, then drill into the worst offender's history:
query AppliedModels($environmentSlug: String!, $first: Int!) {
  environment(slug: $environmentSlug) {
    applied {
      models(first: $first) {
        edges {
          node {
            name
            uniqueId
            materializedType
            executionInfo {
              lastSuccessRunId
              executionTime
              executeStartedAt
            }
          }
        }
      }
    }
  }
}
query ModelHistoricalRuns(
$environmentSlug: String!
$uniqueId: String
$lastRunCount: Int
) {
environment(slug: $environmentSlug) {
applied {
modelHistoricalRuns(uniqueId: $uniqueId, lastRunCount: $lastRunCount) {
name
runId
runElapsedTime
executionTime
executeStartedAt
executeCompletedAt
status
adapterResponse
}
}
}
}adapterResponse is the warehouse adapter's response for that run, returned as dbt™ recorded it in run_results.json. On Snowflake it carries query_id and rows_affected; on BigQuery, job_id, bytes_processed, bytes_billed and slot_ms. That's the join key between a dbt™ model and your warehouse's own query history - which means you can attribute credits or bytes to a specific model, on a specific run, without guessing from timestamps.
runId values are Bolt schedule_run IDs, so you can hand them straight to the Bolt API to pull the full run.
Example 2: alert only on stale sources
query StaleSources($environmentSlug: String!, $first: Int!) {
  environment(slug: $environmentSlug) {
    applied {
      sources(first: $first, filter: { freshnessStatus: "error" }) {
        totalCount
        edges {
          node {
            sourceName
            name
            identifier
            loader
            freshness {
              freshnessStatus
              maxLoadedAt
              maxLoadedAtTimeAgoInS
              criteria
            }
            children {
              uniqueId
              name
              resourceType
            }
          }
        }
      }
    }
  }
}
Filtering on freshnessStatus (pass, warn, error) means the query returns nothing when everything is healthy. That's what you want for an alerting job: run it on a cron, and only speak up when there's something to say. Pulling children in the same request tells you what's downstream of the stale source, so the alert can name the affected models rather than just the source.
The equivalent filters for failures elsewhere are models(filter: { lastRunStatus: "error" }) and tests(filter: { status: "fail" }).
Example 3: put a health signal on a dashboard
Exposures describe how your models are used downstream. Paradime computes a health rollup across all of an exposure's ancestors - worst source freshness, worst run status, worst test result - so you don't have to walk the graph yourself:
query ExposureHealth($environmentSlug: String!, $first: Int!) {
  environment(slug: $environmentSlug) {
    applied {
      exposures(first: $first, filter: { exposureType: "dashboard" }) {
        edges {
          node {
            name
            exposureType
            ownerName
            ownerEmail
            url
            freshnessStatus
            runStatus
            quality
            isHealthy
            healthIssues
          }
        }
      }
    }
  }
}
This is enough to render a trust badge next to a Looker or Tableau dashboard: isHealthy for the state, healthIssues for the explanation, ownerEmail for who to contact.
Example 4: audit documentation and ownership
Two queries, one for what's documented and one for who owns it:
query DocsCoverage($environmentSlug: String!, $first: Int!, $after: String) {
  environment(slug: $environmentSlug) {
    applied {
      models(first: $first, after: $after) {
        totalCount
        pageInfo { hasNextPage endCursor }
        edges {
          node {
            uniqueId
            name
            description
            tags
            meta
            catalog {
              columns { name description type }
            }
          }
        }
      }
    }
  }
}
query ModelsByGroup($environmentSlug: String!, $first: Int!) {
environment(slug: $environmentSlug) {
definition {
models(first: $first) {
edges {
node { name access groupName }
}
}
groups(first: 100) {
edges {
node { name ownerName ownerEmail }
}
}
}
}
}Joining the two gives you a coverage report broken down by team instead of one global number, which is what actually gets acted on.
For full-graph work, the flat lineage feed returns every node with its direct parent edges in one call, so you can reconstruct the DAG locally instead of walking children a generation at a time:
query FullLineage($environmentSlug: String!) {
  environment(slug: $environmentSlug) {
    applied {
      lineage {
        uniqueId
        name
        resourceType
        parentIds
        publicParentIds
      }
    }
  }
}
Pulling it into Python
Most internal tooling starts the same way: a thin client that handles auth and pagination, and then plain dictionaries you can push into pandas, a dashboard, or a model context.
# paradime_discovery.py
import os
import requests
from typing import Any, Callable, Iterator


class DiscoveryClient:
    """Minimal client for the Paradime Discovery API."""

    def __init__(self, endpoint: str, token: str, workspace_uid: str):
        self.endpoint = endpoint
        self.session = requests.Session()
        self.session.headers.update({
            "Content-Type": "application/json",
            "Authorization": f"Bearer {token}",
            "X-Paradime-Workspace": workspace_uid,
        })

    @classmethod
    def from_env(cls) -> "DiscoveryClient":
        return cls(
            endpoint=os.environ["PARADIME_API_ENDPOINT"],
            token=os.environ["PARADIME_API_KEY"],
            workspace_uid=os.environ["PARADIME_WORKSPACE_UID"],
        )

    def query(self, document: str, **variables: Any) -> dict:
        response = self.session.post(
            self.endpoint,
            json={"query": document, "variables": variables},
            timeout=60,
        )
        response.raise_for_status()
        payload = response.json()
        if payload.get("errors"):
            raise RuntimeError(payload["errors"])
        return payload["data"]

    def paginate(
        self,
        document: str,
        select: Callable[[dict], dict],
        page_size: int = 200,
        **variables: Any,
    ) -> Iterator[dict]:
        """Yield every node from a cursor-paginated connection.

        `select` receives the `data` dict and returns the connection,
        e.g. lambda d: d["environment"]["applied"]["models"]
        """
        cursor = None
        while True:
            data = self.query(document, first=page_size, after=cursor, **variables)
            connection = select(data)
            for edge in connection["edges"]:
                yield edge["node"]
            page = connection["pageInfo"]
            if not page["hasNextPage"]:
                return
            cursor = page["endCursor"]
Build an internal documentation report
import json
import pandas as pd
from paradime_discovery import DiscoveryClient

DOCS_COVERAGE = """
query DocsCoverage($environmentSlug: String!, $first: Int!, $after: String) {
  environment(slug: $environmentSlug) {
    applied {
      models(first: $first, after: $after) {
        totalCount
        pageInfo { hasNextPage endCursor }
        edges {
          node {
            uniqueId
            name
            description
            meta
            catalog { columns { name description } }
          }
        }
      }
    }
  }
}
"""

client = DiscoveryClient.from_env()

models = client.paginate(
    DOCS_COVERAGE,
    select=lambda d: d["environment"]["applied"]["models"],
    environmentSlug="production",
)

rows = []
for model in models:
    columns = (model.get("catalog") or {}).get("columns") or []
    documented = [c for c in columns if (c.get("description") or "").strip()]
    meta = json.loads(model["meta"]) if model.get("meta") else {}
    rows.append({
        "unique_id": model["uniqueId"],
        "name": model["name"],
        "has_description": bool((model.get("description") or "").strip()),
        "columns": len(columns),
        "documented_columns": len(documented),
        "column_coverage": len(documented) / len(columns) if columns else None,
        "owner": meta.get("owner"),
    })

df = pd.DataFrame(rows)

print(f"Models with a description: {df.has_description.mean():.0%}")
print(df.sort_values("column_coverage").head(20))

df.to_csv("docs_coverage.csv", index=False)
From here the same DataFrame drives whatever surface your team already uses: write it to a warehouse table and point Looker or Metabase at it, render it with Streamlit, or post the top offenders to Slack every Monday.
Give an AI agent the metadata as context
The API returns JSON, which makes it straightforward to hand a scoped slice of your project to a model as structured context - rather than letting an agent guess at your schema or run exploratory warehouse queries to rediscover it.
import json
import anthropic
from paradime_discovery import DiscoveryClient

MODEL_CONTEXT = """
query ModelContext($environmentSlug: String!, $uniqueId: String!) {
  environment(slug: $environmentSlug) {
    applied {
      models(first: 1, filter: { uniqueId: $uniqueId }) {
        edges {
          node {
            name
            description
            database
            schema
            alias
            materializedType
            compiledCode
            executionInfo { lastRunStatus lastRunError executeCompletedAt executionTime }
            ancestors(types: ["model", "source"]) { uniqueId name resourceType }
            catalog { rowCount sizeBytes columns { name description type } }
          }
        }
      }
    }
  }
}
"""

client = DiscoveryClient.from_env()
data = client.query(
    MODEL_CONTEXT,
    environmentSlug="production",
    uniqueId="model.demo_sales_project.order_items",
)
model = data["environment"]["applied"]["models"]["edges"][0]["node"]

llm = anthropic.Anthropic()
message = llm.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=1500,
    system=(
        "You are a data engineer reviewing a dbt model. "
        "Use only the metadata provided. Do not invent columns or lineage."
    ),
    messages=[{
        "role": "user",
        "content": (
            "Here is the current state of a production model:\n\n"
            f"{json.dumps(model, indent=2)}\n\n"
            "Identify undocumented columns, note anything suspicious in the last "
            "run, and draft the YAML description block."
        ),
    }],
)

print(message.content[0].text)
The pattern works the same way for other jobs: freshness plus lineage for incident triage, modelHistoricalRuns plus adapterResponse for cost review, definition versus applied for spotting drift. The API decides exactly what the agent sees, so it can't invent a column or a dependency that isn't there.
Where DinoAI agents fit
If you'd rather not write and host the polling loop, DinoAI reads the same metadata from the other side.
DinoAI's dbt™ Discovery tools - get_all_models, get_all_sources, get_lineage, get_model_health, get_model_performance, get_node_details, get_exposures and the rest - are backed by the same Bolt-collected artifacts the Discovery API serves. So an agent can answer a metadata question without you writing GraphQL, and it can do so on a schedule.
A Programmable Agent is a YAML file committed to your repo under .dinoai/agents/. The tools allowlist decides what it can reach.
Slack alerts when a source fails to refresh
# .dinoai/agents/freshness-sentinel.yml
name: freshness-sentinel
version: 1

role: >
  Source freshness monitor for the production dbt™ project.

goal: >
  Identify sources whose freshness check is failing, work out what depends on
  them, and post a single actionable summary to Slack. Say nothing when
  everything is healthy.

backstory: >
  You are terse and specific. You name the source, how long it has been stale,
  the downstream models and exposures affected, and the owning team. You never
  post a message that only says everything is fine.

tools:
  mode: allowlist
  list:
    - get_all_sources
    - get_lineage
    - get_model_health
    - get_exposures
    - post_slack_message

slack:
  channel: "#data-alerts"
Then schedule it from Bolt. The command runs natively inside your workspace, so there are no API keys to configure on the schedule:
# paradime_schedules.yml
schedules:
  - name: source freshness sentinel
    slug: source-freshness-sentinel-a1b2c3
    description: "Hourly source freshness sweep, alerts to #data-alerts"
    owner_email: data-team@acme.io
    environment: production
    git_branch: main
    commands:
      - paradime dinoai --agent=freshness-sentinel --message="Check every source for failing freshness. For each failure, report how long it has been stale, which models and dashboards are downstream, and who owns them. If nothing is failing, post nothing."
    schedule: "15 * * * *"
    timezone: UTC
You can also trigger the same agent through the API with triggerDinoaiAgentRun when you want it inside a workflow you already orchestrate - Airflow, a Lambda, an incoming webhook.
Turn documentation gaps into Jira or Linear issues
The Discovery API can tell you a model has no description. An agent can go further: read the SQL, check whether an issue already exists, and file one with a useful title and body.
# .dinoai/agents/docs-gap-filer.yml
name: docs-gap-filer
version: 1

role: >
  Documentation coverage auditor for the production dbt™ project.

goal: >
  Find mart models and their columns that lack descriptions, and file one
  ticket per owning team with the specific gaps listed.

backstory: >
  You check for an existing open ticket before creating a new one. You group
  gaps by owning team rather than filing one ticket per model. Every ticket
  lists model names, column names and the model's file path.

tools:
  mode: allowlist
  list:
    - get_mart_models
    - get_node_details
    - get_all_models
    - read_file
    - ripgrep_search
    - list_linear_issues
    - create_linear_issue
    - post_slack_message

slack:
  channel: "#analytics-engineering"
Swap list_linear_issues and create_linear_issue for list_jira_issues and create_jira_issue if you're on Jira. Run it weekly rather than hourly - documentation debt moves slowly, and a weekly ticket gets read while a daily one gets filtered.
The same idea covers a few other recurring jobs: a test-coverage auditor that files tickets for mart models without a primary key test, a performance reviewer that opens an issue when a model's runtime regresses across recent runs, an ownership auditor that flags public models with no group.
Two rules worth keeping. Use allowlist mode in production so an agent can't reach beyond its job. And give it a clear instruction about staying quiet - an agent that posts every hour whether or not anything happened stops being read within a week.
Getting started
- Generate an API key with the Discovery API Viewer capability, and grab your API endpoint and workspace UID. Add Catalog Admin too if you want to trigger
refreshCatalogon demand. - Confirm the environment you want to query has at least one completed Bolt run - the API is populated from Bolt, so an environment with no runs returns nothing.
- Run the
EnvironmentOverviewquery above.resourceCountsis a fast sanity check that you're pointed at the right project. - Pick one of the examples and adapt it. Freshness alerting is usually the fastest thing to get value from.
Full reference, including every filter and the refreshCatalog mutation: Discovery API documentation.
Interested to Learn More? Try Out the Free 14-Days Trial
One AI-native workspace to build, ship, and monitor dbt™ — without the tool sprawl.
More Articles
Join industry leaders winning with DinoAI agents
Data engineers and analysts at the most AI-native startups and enterprises use Paradime's DinoAI agents everyday to become market leaders.